

About this question
I am using PostgreSQL.
I have a table with 2 columns in this example:
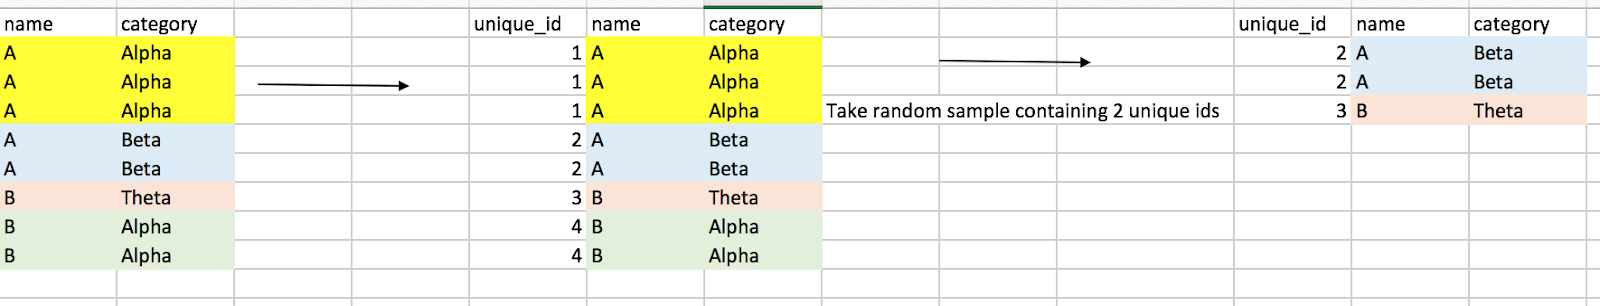
I want to add a new column with a unique id corresponding to partitions by name and category as shown in the result. Then, I want to take a random sample choosing 2 (or more) unique ids because under each unique id, there will be a lot of other historical data.
I have tried this so far, but I get 1s for everything. I'm missing something really simple here, but how do I correct my mistake? I have to do this operation for several million rows in the real table.
SELECT
  dense_rank() over (partition by name, category order by category) as unique_id,
  *
FROM
 example_table
After this, presumably I'll have to use RAND() somewhere but how do I do this?
This is my naive approach to get the solution in the above pic.
with ranks (
  ...
)
select * from ranks where unique_id = 2 or unique_id = 4



